From 2019 to 2025, data improvements contributed 12x more compute efficiency gains to pretraining than model improvements (3.7x), but the real value of model research was enabling ever-larger scale of training.
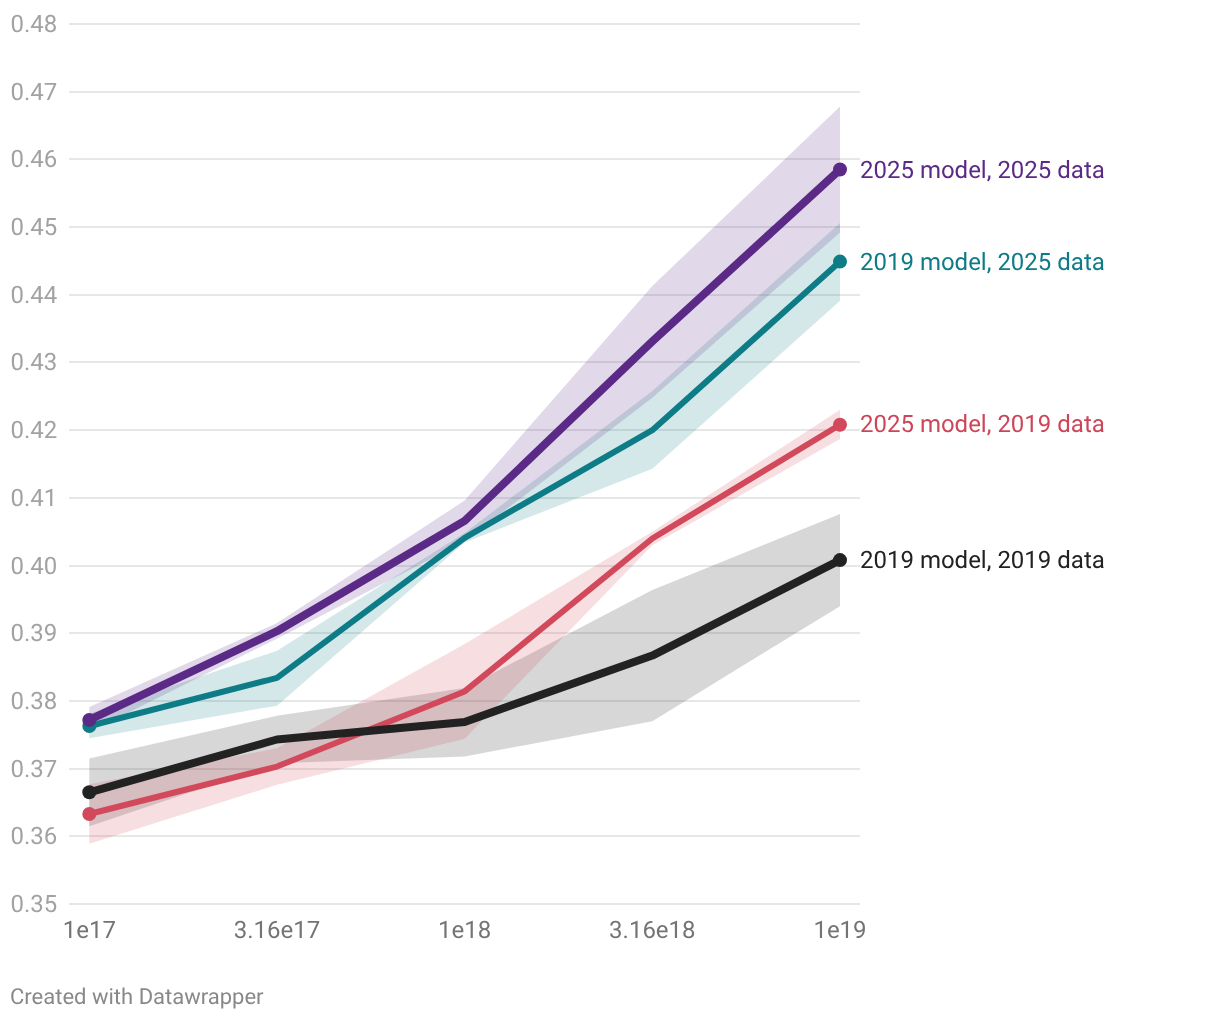
Everyone assumes AI got smarter mainly because of better models. But a new study suggests that over the past six years, most pretraining progress came from data: a 2019 model trained on 2025 data far outperforms a 2025 model trained on 2019 data.
The authors trained every combination of each year's representative model recipe and data corpus, then compared their scores on a broad benchmark. The result is striking: data improvements delivered more than three times the efficiency gains of model improvements.
Model gains: letting the big ship sail
But don't write off models. Their real contribution wasn't fewer FLOPs; it was making training larger possible at all — fixing gradient explosions, vanishing memory, and slow training. Without model research, no amount of data would help.
Is there more cargo left
This raises a bigger question: data curation looks like eating a fixed pie — the internet isn't growing on demand. Can synthetic data fill the gap? That's the next big unknown.
Bottom line: for pretraining, picking better data beats tweaking models, but the ship's size still limits how much cargo you can load.
Curated from high-quality sources, with concise summaries and key takeaways.

